


Over the last two years, the integration of large language models (LLMs) into business operations—spanning support, analytics, development, and automation—has surged. However, cybercriminals are increasingly exploiting the gap between expectations of LLMs and their actual behaviors, with prompt injection emerging as a prevalent, powerful attack vector. Prompt injection remains the top LLM-specific vulnerability identified by the OWASP LLM Top 10 (2025), due to LLMs' struggle to differentiate instructions from data reliably, leading to manipulation risks.
Reports like CrowdStrike's 2026 Global Threat Report reveal that attackers injected malicious prompts into generative AI tools at over 90 organizations in 2025, enabling theft of credentials and cryptocurrency. Real-world cases, including Slack AI and Microsoft 365 Copilot vulnerabilities, show prompt injection’s tangible threats, resulting in data leaks and unauthorized access. These incidents have led to patches but highlight the persistent dangers.
Modern prompt injection techniques have evolved, now targeting multi-agent systems, retrieval-augmented generation (RAG) pipelines, model routers, and long-term memory features. Enterprises face challenges with LLMs struggling to interpret instructions, context, metadata, and user intent accurately, creating opportunities for manipulation.
Key attack methods include cross-model prompt injection, RAG supply chain poisoning, agent hijacking, context overflow, memory poisoning, and model-router manipulation. The implications are broad, affecting customer-facing systems, internal tools, automation workflows, and data governance, with risks ranging from unauthorized actions to workflow corruption.
To defend against these threats, businesses should constrain model permissions, segment untrusted content, require human approval for critical actions, verify content provenance, harden model routers, and ultimately adopt a mindset that treats LLMs as untrusted components to safeguard AI security.
Prompt injection dominates AI threats because it exploits fundamental LLM behaviors. Until enterprises adjust their approach to treating LLMs, this vulnerability will remain their biggest AI security challenge.
Author: Julie Brunias, AI Security Architect.

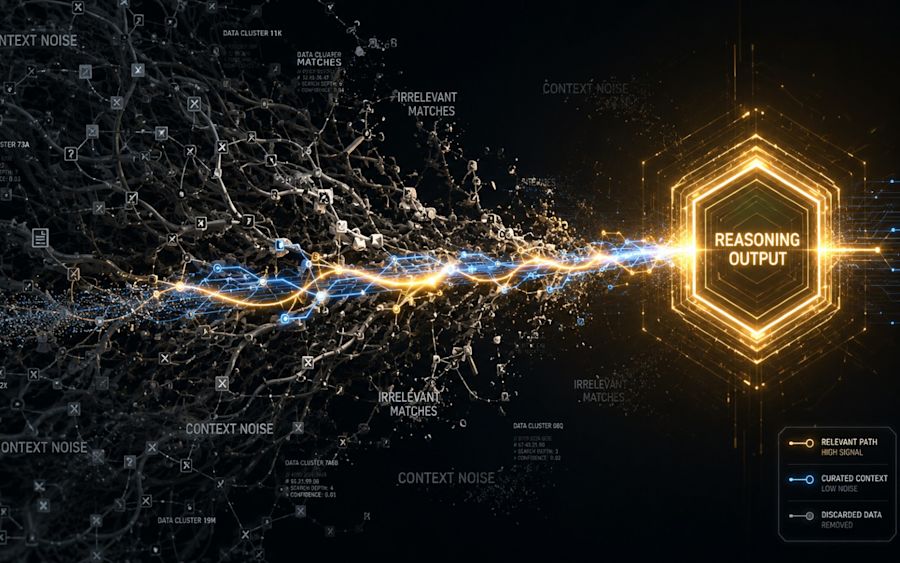
Long-horizon reasoning in AI reveals a major challenge: context windows fill quickly, and typical retrieval systems return more noise than useful information. Researchers at the National University of Singapore have introduced MRAgent, a novel memory framework that breaks away from the traditional retrieve-then-reason approach. Instead, MRAgent employs an active memory reconstruction strategy, dynamically building memory during the reasoning process by accumulating evidence step-by-step.
Traditional retrieval methods rely on static structures and fixed similarity scores, which limits their flexibility and often floods the AI’s context with irrelevant data. MRAgent, inspired by cognitive neuroscience, uses a Cue-Tag-Content system to organize memory as an interactive graph. This approach allows it to explore and prune memory paths intelligently during query processing, significantly reducing token usage and computational cost.
For example, when asked how someone used prize money after winning a video game tournament, MRAgent picks up fine-grained cues from the query, navigates relevant tags, retrieves pertinent memories, and gradually hones in on the answer, discarding irrelevant information along the way.
Benchmarked against similar frameworks like A-Mem, MemoryOS, LangMem, and Mem0 on long-horizon tasks, MRAgent not only outperformed them in accuracy but also drastically cut token usage to 118K per query compared to LangMem’s 3.26 million. Runtime was nearly halved, proving its efficiency for real-world applications.
While setting up the Cue-Tag-Content database requires thoughtful design, MRAgent includes an automated pipeline that distills raw user interactions into the graph without manual tagging. The framework’s code is openly available on GitHub, offering practical tools for developers to build scalable, context-aware AI agents.
Anthropic's growth team was recently advised to hire more product managers to keep pace with a significant shift caused by Claude Code, which has essentially tripled engineering productivity. The bottleneck in software development has shifted from coding speed to deciding what to build, necessitating a deeper product focus within engineering teams.
Historically, engineers followed a linear process: learning deeply about technology, writing code, and escalating issues as needed, while product managers managed the project funnel. This traditional division is now outdated as recent innovations compressed and transformed the engineering workflow through several eras—from relying on Stack Overflow to AI-enabled IDEs and spec-driven development.
Today, engineers produce code faster than ever, but the need for clear product direction and decision-making has intensified. Companies like LinkedIn and Anthropic are adapting by blending product management skills with engineering roles.
Fundamental technical skills remain critical in verifying and reviewing AI-generated code to prevent costly mistakes. Furthermore, successful engineers now engage directly with product funnels—interacting with customers, understanding use cases firsthand, and proactively contributing to idea generation and prioritization.
The future rewards engineers who can identify valuable projects, validate them, and manage rapid delivery through AI-assisted workflows. Those who rely solely on traditional tickets risk being left behind.

Liquid AI, created by former MIT computer scientists, has introduced its smallest AI language model yet, LFM2.5-230M. This 230-million-parameter model is engineered for on-device agentic workflows, enabling it to run efficiently on smartphones, laptops, and robotics. Despite its small size, it surpasses larger models—more than four times its size—in data extraction tasks, outperforming Alibaba's 800M parameter Qwen3.5-0.8B and Google's 1B parameter Gemma 3 1B.
LFM2.5-230M focuses on developers and engineers building lightweight data extraction pipelines and edge systems. It operates under a dual-use commercial license, free for entities earning below $10 million annually, while larger enterprises require a paid license. The model’s unique LFM2 architecture combines gated short-range convolutions with grouped-query attention, allowing high inference speed and a memory footprint below 400MB. It supports a large 32K context window for processing long documents or data streams.
Performance benchmarks show the model's efficiency, decoding 213 tokens per second on a Samsung Galaxy S25 Ultra and 42 tokens per second on a Raspberry Pi 5. It excels specifically in AI ETL tasks, offering a cost-effective alternative to expensive cloud-based models by running locally. LFM2.5-230M scores notably well on benchmarks like BFCLv3 and CaseReportBench, demonstrating superior tool-use and data extraction performance compared to larger models.
The model also serves advanced research needs, demonstrated by its deployment on a Unitree G1 humanoid robot for on-device command processing and multi-step planning. The base and post-trained models are available on Hugging Face, with broad support for popular inference platforms.
Liquid AI released LFM2.5-230M under a dual-use license that is free for smaller users but restricts commercial use by companies earning over $10 million annually, requiring paid agreements for larger enterprises. This approach balances open accessibility with commercial protection.

OpenAI has unveiled the GPT-5.6 series, featuring three specialized models—Sol, Terra, and Luna—each tailored to different enterprise needs. Sol is designed for complex coding and cybersecurity tasks, Terra targets high-volume business workflows, and Luna is optimized for everyday, cost-efficient operations like summarization and drafting. Initially, these models will be accessible to roughly 20 select organizations following coordination with the U.S. government, in line with a recent executive order establishing AI safety benchmarks. OpenAI emphasizes a phased release to ensure security and compliance, introducing innovative features like extended reasoning modes and subagent workflows. Pricing varies, with Sol priced at $35 per million tokens, Terra at $17.50, and Luna at $7.00. The models demonstrate significant performance improvements across reasoning, biology, and cybersecurity tasks, supported by advanced safety measures and a revamped caching system for cost predictability. This release reflects the increasing intersection of AI innovation with national security frameworks, highlighting the challenges enterprises face in accessing cutting-edge AI tools amid regulatory scrutiny.

An endpoint security agent is unable to detect its own absence, creating significant visibility gaps. The 2026 Axonius Actionability Report, surveying 662 IT and security experts, reveals that 12.7% of devices in a median inventory of nearly 300,000 lack their expected security agent. This invisible margin leaves autonomous security systems and SOC teams working with incomplete threat coverage, which poses risks as these agents operate at machine speed without human oversight. Several studies confirm widespread gaps: 88% of companies report AI-related security issues, and only a small fraction approve live AI agent deployment fully. Industry leaders emphasize that unknown assets in the network — often termed 'dark matter' — significantly undermine security efforts, with many organizations seeing only half of their actual environment. Tackling these gaps requires combining three approaches: a dedicated integration layer for real-time inventory, native EDR/XDR platform intelligence, and continuous CMDB reconciliation. A practical five-gate checklist helps determine if EDR and asset data is ready for autonomous remediation, focusing on inventory accuracy, AI service management, ownership mapping, and coverage verification. For organizations aiming to deploy autonomous agents safely, running out-of-band discovery, applying consistent ownership tags, and killing reliance on self-reported metrics are critical steps to closing these blind spots. Without addressing these data gaps, autonomous security actions could proceed blindly, risking operational failures and increased attack surfaces.

London-based startup Mindstone has launched Rebel, an innovative AI agent orchestration platform designed to optimize enterprise AI usage. Unlike typical cloud-centric systems, Rebel employs a local-first architecture, storing agent workflows and memory in markdown files to ensure transparency, flexibility, and data sovereignty. It dynamically routes different workflow steps to the best-suited AI models—balancing local and cloud resources—for cost efficiency, security, and compliance. This modular approach allows enterprises to assign complex reasoning to powerful cloud models while managing sensitive data locally. Rebel’s shared-memory design fosters collaboration, letting teams build on each other's work. Additional features include reusable workflow "skills," automated background tasks, and an ROI dashboard for measuring impact. Released under a Fair Source license, Rebel supports organizations up to 100 users for free, scaling commercially beyond that. Mindstone’s approach addresses common enterprise AI challenges around security, model management, and vendor lock-in, enabling companies to seamlessly adopt AI without sacrificing control or transparency.

OpenAI has released a significant update to its popular GPT-5.5 Instant model, the default engine for the free ChatGPT version. This update, rolled out first to paid subscribers and now available to free users since June 25, boosts the model's ability to understand user intent, especially in complex decision-making situations such as planning, shopping, and local recommendations. The model now handles overlapping constraints more effectively, adapts to clarifications during conversations, and offers a more natural conversational tone, moving away from rigid, robotic responses. The update is accessible to developers through the updated chat-latest API alias, which showcases the latest Instant improvements but differs from the stable gpt-5.5 production model. Enterprises benefit from a smarter and more context-aware ChatGPT, enhancing reliability for research, planning, and customer interactions, though they should remain cautious about observability and system logs. Overall, this update marks a shift toward more intuitive, goal-aware AI systems that improve both consumer and developer experiences.

AI agents are becoming more capable of autonomously handling business tasks, yet IT leaders remain cautious about granting them access to critical enterprise systems. One core issue is how AI reliability is assessed. Traditional metrics like EVAL scores provide only a limited snapshot of performance and often miss factors like consistency across varied prompts and environments. Bryan Silverthorn, director of Amazon’s AGI Autonomy research lab, explained that their team is shifting focus beyond performance benchmarks to a framework emphasizing consistency, robustness, predictability, and safety.
Amazon’s approach includes decoupled systems, such as sandboxed environments where AI agents suggest changes that humans review before implementation. This method helps build trust, especially in sensitive sectors like finance, where the risks are high. VentureBeat’s Q2 Pulse Research showed that only 4% of senior tech leaders fully trust model guardrails, with many concerned about unauthorized access and prompt manipulation.
At VB Transform 2026, Silverthorn will detail Amazon’s method of engineering reliable agentic AI, guiding companies from simple agent wrappers to advanced multi-tool architectures capable of self-correcting mid-task. The event also features sessions on safe AI deployment, including insights from Waymo on building efficient, safe AI for real-world applications.
If interested in attending, senior technology leaders can request complimentary passes to VB Transform 2026 or purchase tickets online.
Drug discovery remains a slow and fragmented process, with an alarming failure rate of 90% to 95%. It often takes over a decade and up to $1 billion to bring a single successful drug to market. While generative AI has offered new solutions, Stanford researchers have advanced the field with autonomous AI "scientist" agents that simulate the entire drug development lifecycle. Led by James Zou, these thousands of AI agents operate within a unified framework, handling discovery, safety testing, clinical trial design, and more, preserving project continuity and context. The hierarchical system uses a chief scientist agent to oversee task delegation among specialized agent teams. Data integration spans from genomics and FDA chemistry to trial databases, enabling sophisticated synthesis and analysis powered by models like Claude and specialized fine-tuned versions. Zou’s startup, Human Intelligence, built on this research, is currently valued near $1 billion. At VB Transform 2026, Zou will unveil strategies for managing complex multi-agent workflows, transforming enterprise data to be agent-native, and employing human auditing for reliable AI outputs. Another event highlights how Zillow boosted engineering productivity by 40% through trustworthy agentic AI foundations. Interested leaders can register for VB Transform 2026 and inquire about complimentary passes for senior tech executives.
